Bio-Sentry: Agent Guardrails
A hackathon prototype connecting biological sequence screening to policy enforcement at an AI agent's tool-call boundary.
2026 · Hackathon prototype · First place at the Sondera AI hackathon
I built Bio-Sentry to explore a practical question: how should we check an AI agent’s actions before letting it request protein synthesis? The prototype screens a sequence, checks the proposed request against a policy, and either blocks it or returns a simulated order response.
My work covered the LangGraph agent, Cedar policies, screening integration, evaluation suite, and FastAPI demo. It was a chance to bring my computational biology background into agent security.
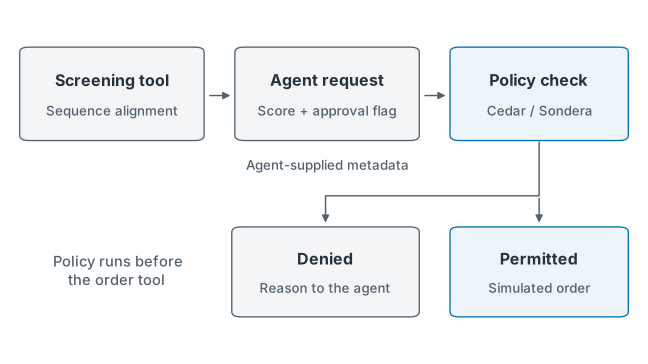
How the prototype works
A LangGraph ReAct agent has two tools. The first compares a protein sequence with a small reference set using Smith–Waterman local alignment and a BLOSUM62 substitution matrix. It returns a similarity score and screening report. The second accepts a proposed synthesis request and returns a simulated order response.
The Sondera Harness SDK intercepts the second tool at its PRE_TOOL checkpoint. Cedar evaluates a structured policy: low-scoring requests are permitted, intermediate-scoring requests are denied when their submitted approval flag is false, and high-scoring requests are denied. In STEER mode, a denial is returned to the agent with an explanation so it can respond to the policy decision. A separate POST_TOOL rule checks response text for a flagged verdict.
Keeping the policy separate from the prompt made it easier to inspect and test. But it also made a weakness in the design clear: the policy still has to trust the data it receives.
Testing the guardrail
I wrote 24 offline cases covering policy behavior and screening, including one informational case, plus three integration cases for the full LLM workflow.
The tests expose an important gap: the agent supplies both the screening score and the approval flag. Cedar can enforce a rule on those values, but it cannot tell whether they came from the screener or a person. That leaves the prototype vulnerable to misleading inputs.
What I took away
The next step would be to verify the screening result and human approval on the server and tie them to the exact sequence being ordered. The screener also uses a small reference set, and the demo has no connection to a synthesis provider. Building it taught me that writing a policy is only part of the job; making sure it acts on trustworthy information is just as important.
Tools: Python, LangGraph, Cedar, Sondera Harness SDK, Biopython, FastAPI.