LLM Cell-Type Annotation
Benchmarking LLM agents for reference-free cell-type annotation, with explicit checks for workflow failures and hallucinations.
2025 · ICLR MLGenX workshop paper · Penn Immune Health Hackathon winner
Paper · OpenReview · Poster
I benchmarked LLM agents that assign cell-type labels to clustered spatial gene-expression data without a fixed reference atlas. I ran the model comparisons and reviewed their outputs: did they finish, did they use the data, and did their labels agree with expert annotations? We wanted to see how much of the analysis an agent could handle with minimal guidance.
From expression data to labels
The system uses a single LLM agent built with ag2, combining local Python execution with tools for querying PubMed and NCBI Entrez. Its system prompt gives a general workflow: explore the dataset, formulate and execute a plan, then summarize findings. The same prompts were used with Claude 3.5 Sonnet, o3-mini with high reasoning, and GPT-4o.
We gave each agent precomputed differential-expression data for each cluster, the tissue identity, and a request for cell-type labels. It could use its biological knowledge or search PubMed, but received no further help during the run. Here, reference-free means that we did not supply a fixed annotation atlas.
Evaluating the workflow
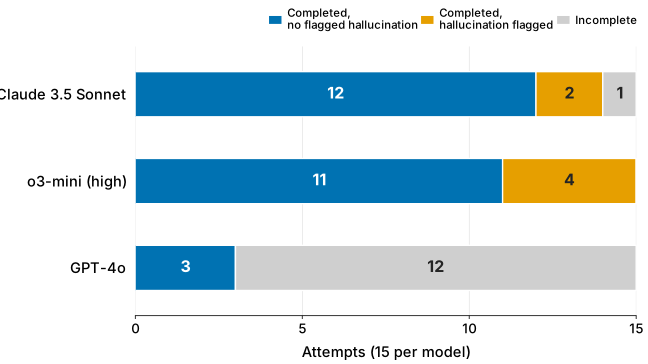
The benchmark covered three 10x Genomics Visium HD datasets: human tonsil with reactive follicular hyperplasia, healthy mouse kidney, and healthy mouse brain. Each was divided into ten clusters using k-means in Loupe Browser. We made five attempts per model per dataset, giving 45 attempts overall.
A run counted as complete when its final message contained ten cluster labels. A completed run was flagged as hallucinated when the conversation showed that its labels were not appropriately derived from the supplied data. Common failures included plausible sample labels based only on the tissue and labels inferred from invented gene signatures. Coarse but data-grounded labels instead received lower alignment scores.
How well did the labels match?
Human pathologists established reference labels using expression data and histology; the agents had no histology images. Predictions were manually rated on an ordinal scale from 1 to 4, from complete misalignment to perfect alignment. The table reports mean cluster scores only for completed runs without flagged hallucinations; parentheses give the number of qualifying runs, each containing ten labels.
| Model | Tonsil | Kidney | Brain |
|---|---|---|---|
| Claude 3.5 Sonnet | 3.6 (4) | 3.8 (3) | 3.5 (5) |
| o3-mini high | 2.6 (4) | 3.6 (3) | 3.5 (4) |
| GPT-4o | 2.4 (2) | 2.6 (1) | — (0) |
Six of the 32 completed runs contained hallucinations, about 19%. Looking only at the label scores would have missed both those failures and the runs that never finished.
What I learned
This was a small study of three datasets with manual scoring, so broader comparisons with established annotation methods are still needed. What stayed with me was how convincing an answer could look even when the agent had barely used the data. Reviewing the analysis behind each answer was as important as scoring the labels themselves.