VHH Design and Evaluation
Designing VHH candidates for CAR T cells and testing whether their predicted confidence and binding surfaces survive re-evaluation.
2026 · Computational study and construct development
I’m designing single-domain antibodies, or VHHs, for use as the antigen-binding part of CAR T cells. Much of my work asks what happens after a model proposes a promising sequence: does it still look promising when we evaluate it another way?
I built the design and evaluation workflow around existing models, from choosing target sites and running predictions to comparing the surfaces each binder was predicted to contact. I also worked on turning selected sequences into experimental constructs.
From design to separate evaluation
Using mBER, an AlphaFold2-Multimer-guided VHH design framework, the campaign generated 6,047 unique sequences across five targets: EpCAM, mesothelin, B7-H3, PSMA, and CD19. Four intended binding sites per target gave 20 design sites in total.
I evaluated a confidence-stratified subset of 350 designs spanning all 20 sites: 100 each for EpCAM and CD19, and 50 each for the other targets. All had reached a design-time interface confidence score, ipTM, of at least 0.5. This was a study of promising-looking candidates, rather than a representative sample of everything generated.
Each VHH–antigen complex was predicted again with AlphaFold 3, Protenix, AlphaFold2-Multimer, and Chai-1. The primary comparison supplied the same antigen crop used during design, without homologous sequence alignments or structural templates. This let me test the designs without the structural guidance they had received during optimization.
High design confidence did not consistently persist
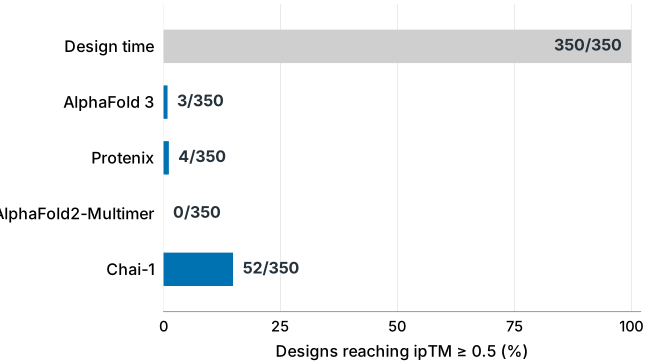
Only 3, 4, 0, and 52 of the 350 designs, respectively, reached ipTM 0.5 on re-evaluation. The median score fell from 0.653 during design to 0.090–0.234 across the four predictors. 295 designs fell below the threshold in all four, and none reached it in all four.
The inputs change the predicted interface
Confidence was only one part of the analysis. I compared which antigen residues contacted each VHH, using Jaccard similarity to measure overlap and averaging the six predictor-pair comparisons per design.
Holding the full antigen ectodomain fixed, removing the target sequence alignment reduced agreement for 294 of 350 designs. With alignments absent, restricting the antigen to the design crop increased agreement for 291 of 350. Simply changing the information supplied to the models changed where they predicted binding. Restricting the available surface made them agree more, but that alone doesn’t tell us which pose is right.
Where the project is now
We’ve progressed to assembling constructs and checking their sequences. Binding assays and tests of CAR function are the next steps.
The confidence drop doesn’t tell us that these candidates fail to bind. The models use different score scales, and re-evaluation changes the structural guidance and sampling used during design. For me, the useful result is knowing how much the apparent promise of a design can depend on how we choose to evaluate it.
Tools and methods: mBER, AlphaFold 3, Protenix, AlphaFold2-Multimer, Chai-1, Python, GPU batch workflows, structural contact analysis, and experimental construct design.